Watch agents rehearse your release.
For anyone who builds a web app: pick a real app below. Every turn, stop, and result comes from a saved browser run you can inspect.
Repair loop / outside app / NVIDIA Nemotron Nano
Recorded run, 26 Oct 2026A visitor hit a 404. The fix was proven with the same goal.
Overturn is a live public app by the same author. Its menu works on Vercel only because of a rewrite rule. Served as plain files, as any other host or a local preview would, About answers 404. A Nemotron visitor found that, the loop handed back a test, and the fix was checked by trying the same goal again.
Goal given to the visitor: Open the About page and read why Overturn exists
 1 · Visitor stuck
Clicked About: 404. Tried Why this exists: 404. Gave up:
Replay every screenerror page blocked why this exists link
- 2 · Test handed back, red
AssertionError: clicking 'ABOUT'
opened a page that answered 404
Run on the original commit bd6a868.
Download the test Red log - 3 · The fix
- href="/about"
+ href="/about.html"
Same change for Market and Story in 5 files. Applied as its own commit dd55810.
Download the patch - 4 · Same test, green
1 passed
On the fixed commit. Also green on the deployed original, so the fault depends on the host.
Green log 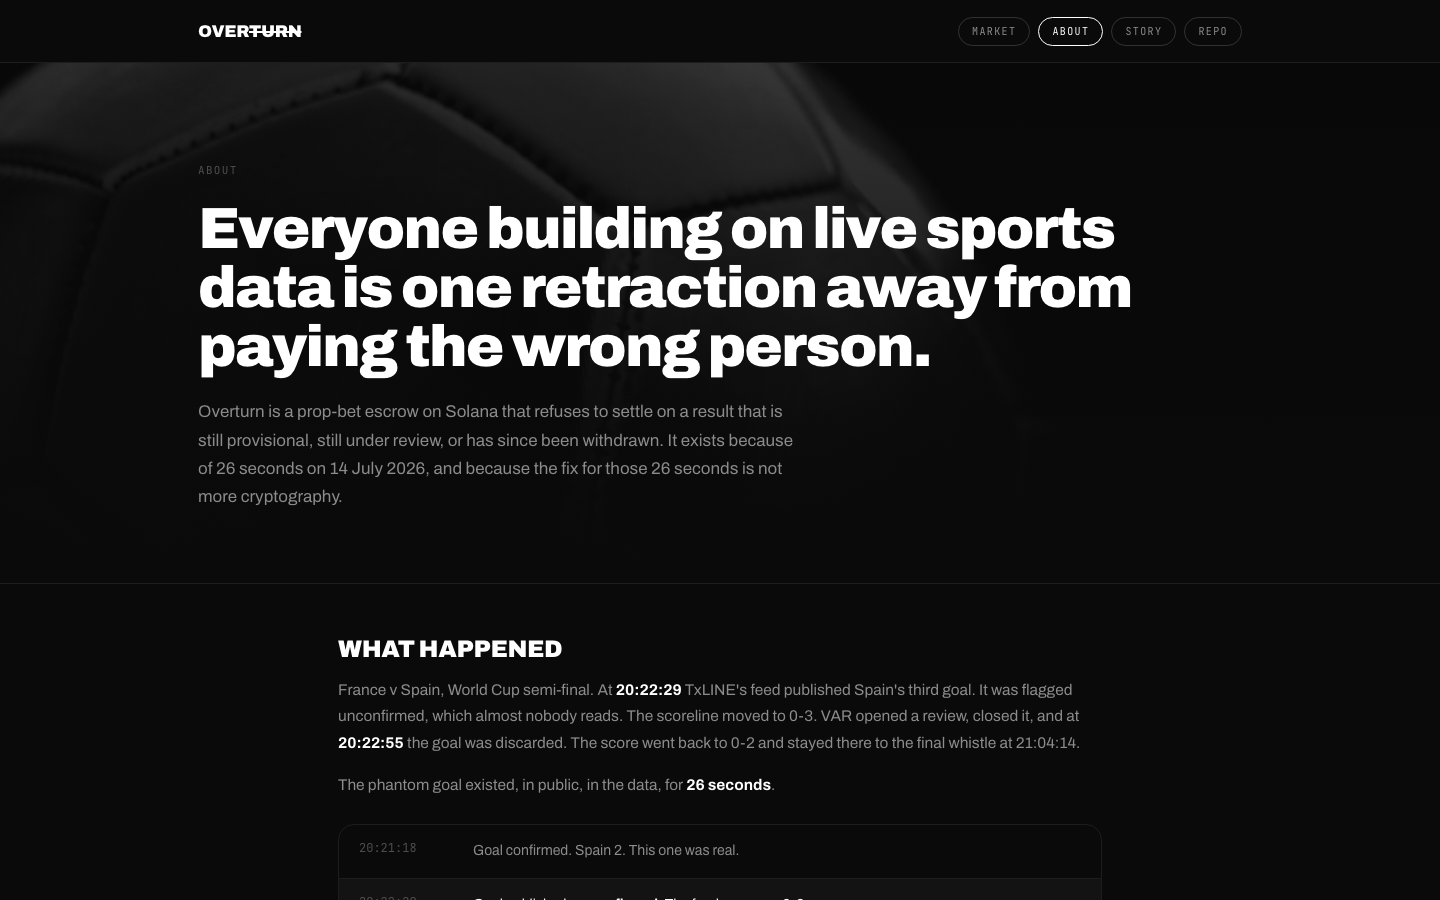 5 · Same goal, reached
A fresh Nemotron visitor opened About; a second call agreed the screen shows why Overturn exists.
Replay every screen
Model: nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B through Nebius Token Factory. 13 calls, every reply with usage and that model id: 16,317 prompt and 617 completion tokens, 0.00113 USD at listed rates, not an invoice. This page replays that run. It makes no model call and repairs nothing.
Check it, or run it on your own app
From this project's source, with Python, git and Playwright Chromium. No key: rebuild both commits from GitHub and rerun the test, red then green.
python -m sim.repair_loop recheck examples/overturn
Your own static site, your own Token Factory key. Two Nemotron visits, each stopped at your cap.
CONFIRM_SPONSOR_SPEND=RUN python -m sim.repair_loop run --repo URL --ref COMMIT --site-dir web --goal "..." --patch fix.patch --visitor nemotron --run-cap-usd 0.05 --output ../repair-run
Limits: static sites served as files; one visitor per side, so this is a reproduction and a rerun, not a success rate. Visitors are models, not people, and only read.
The mission board / NVIDIA Nemotron
Follow the work.
Replay a real visit. Inspect the evidence. Then rehearse your own app.
Loading recorded visitor actions.
Source: puppytime-lost, retained browser run. Playback uses recorded step timing, compressed only between stages. No new model call. This is separate from the app batch below.
Inspect this replay, screens and returned check ↗Fresh-five app missions
Source batch: browser launch failed for each scoped app. These are tester failures, not app defects.
Reading the local batch store.
Loading the scoped plan.
Run with your own key on your machine
Enter your Nebius key in the local runner's hidden prompt. The website never receives it. Page text and screenshots can go to the model provider.
python3 -m sim.app_batch --store /private/tmp/nvidia-app-runs --stop-usd 1 --execute
The amount is your chosen spending stop, not measured cost. Follow RUN.md for setup, then serve the same store to see its saved states here.
Past batches and recorded runs
Recorded release rehearsal
Three visitors. One job. Every path kept.
Job: Open the Donate page
2 of 3 test visitors got the job done in one try. 1 got stuck.
Source run: puppytime-lost · 3 retained visitors · playback makes no model call.
Each colour is one retained visitor. Lines stay visible when motion is reduced.
- 1LandSee the swarm working
- 2Pick an appChoose a retained run
- 3Watch rehearsalFollow every agent path
- 4Read resultOpen evidence and the check
Fresh outside evidence
Three public tools. Three visitors each. One checked task.
- Outside tools
- 3
- Agent attempts
- 9
- Checked passes
- 2/9
Fresh agent attempts on installed releases of three public tools. A failure is not called a tool defect when the canonical control passes. No earlier tool trial or cached case is substituted here.
List only the file paths changed from tag fixture-base to tag fixture-head, one path per line.
2 of 3 visitors completed the checked task. 1 visitor response failure; the tool's canonical control passed.
git version 2.50.1 (Apple Git-155)Find the exact fixed string ERROR_TOKEN in this directory, include line numbers, and respect .ignore.
0 of 3 visitors completed the checked task. 3 visitor response failures; the tool's canonical control passed.
ripgrep 15.2.0 (rev e89fff89ac)Read records.json, sort the records by name, and return each name and value as tab-separated text.
0 of 3 visitors completed the checked task. 3 visitor response failures; the tool's canonical control passed.
jq-1.7.1-appleTry it yourself
One URL. One job. Three visitors.
Start with a staging URL now. GitHub repo import needs OAuth registration before it can be enabled.
What the field measures
ToolBench tests API use at scale. BFCL tests function choice, arguments, multi-turn use, and agentic tasks. ToolSandbox checks stateful progress. This project asks a narrower release question: with the task, model, seeds, and checker held still, did the proposed tool change help?
Source: web/landing/outside-run.json. Each pass is an exact output check, not a model claim.
122 real hackathon apps, 113 hackathons
We cloned each Devpost entry unedited and served it on our machine. Three Nemotron visitors got one task each: open a page from the app's own menu. These are the five ways they got stuck. Only the first is a fault in the app. The other four are limits of our test setup or of the model, and we name them so they are not counted against the app.
- App defect
A link to a page that is not there
23 visitors in 10 apps
The link answered 404. In 2 of these apps the page is missing from the published repo. We fixed both below, with AirIQ from an earlier run.
Replay: EduNova AI - Our setup
A server app served as plain files
39 visitors in 14 apps
Links such as /login need the app's own backend, and we did not start it.
Replay: Blaze - Our setup
A click we could not make or could not see
101 visitors in 50 apps
The button was off the screen or covered, or it worked but changed nothing we compare.
Replay: Liar's Dice - Our setup
Stopped at a sign-in page
43 visitors in 15 apps
The visitors only read and never sign in, so they stopped where a page offered an account.
Replay: StreetEats - The model
Lost on a working app
107 visitors in 51 apps
The link worked, but the visitor picked other links and ran out of steps.
Replay: PuppyTime
Some visitors did get through. In 76 apps at least one visitor reached the page it was asked to open. At first the judge confirmed 25, because it never took a page's own heading as evidence. After that rule was fixed for "open a page" tasks, it confirmed 44, or 46 if two weak name matches are counted: C-HUD Vision, whose page shares the app's name, and bytekode, where "Join" matched the heading "Join Socials". Source: [6].
Counts are stuck visitors and the apps they were in, from the per-visitor causes of the 22 October run. One visitor can be stuck in one way only; one app can show several ways. Source: [6].
| App | Before | The change | After |
|---|---|---|---|
| AirIQ | 3 visitors hit a 404 | Add the About Us page the menu links toThe repo publishes no licence. | All 3 open the page |
| EduNova AI | 2 visitors hit a 404 | Point the sidebar links at pages that existThe repo publishes no licence. | No visitor hits a 404; test green |
| Water Buddy | 2 visitors hit a 404 | Remove the link to a folder that was never publishedThe repo publishes no licence. | No click answers 404; test green |
All 15 recorded swarms are in the studio, with every screen, path and the test each one hands back.
Watch a recorded swarm then press Ask Nemotron now for a live explanation
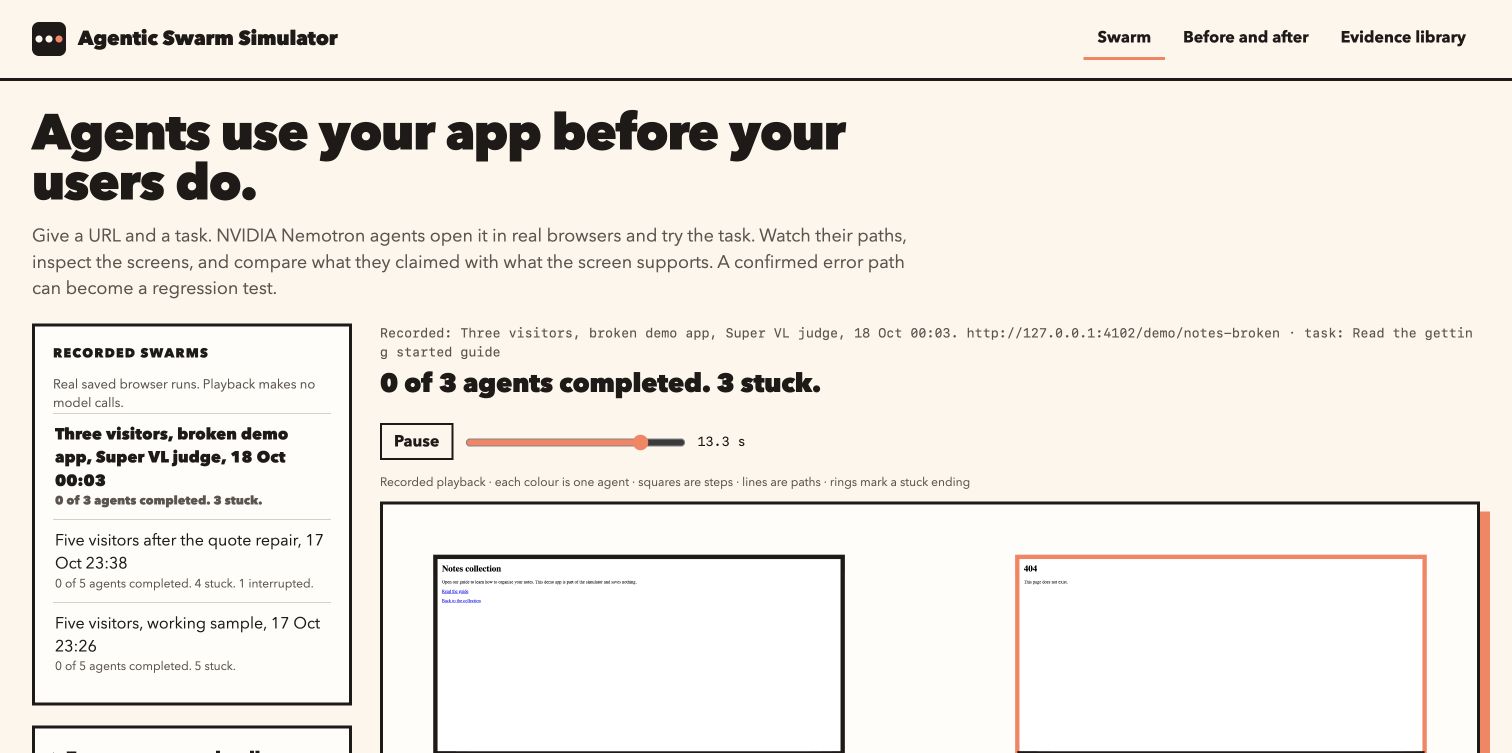
Example. Three agents tried to read the getting started guide on a demo notes app whose guide link is broken. All three hit the same Not found page and stopped there. You see each agent's path, the red screen, what it said versus what the screen shows, and a Playwright test of the stuck path. The honest run on a working sample app, where 0 of 5 finished, sits next to it in the same list. Or watch the 75-second replay.
About this note. Agentic Swarm Simulator sends goal-driven model visitors through a real app, records every screen and decision, and turns a confirmed failure path into a check your team can run again. Below: the method, the two model roles, the recorded results so far, and what the public build does and does not do.
1The problem
You know the route through your app. A new visitor does not.
Give the simulator one URL and one job. A small cast of model visitors opens the app in separate browsers and tries to finish the job. You see what each visitor read, clicked, missed, and claimed. A second model checks the screen evidence. The result keeps failures visible instead of turning them into a polished score.
2Who it is for
A release check for teams that ship fast.
- Founder shipping an agent-built app. Check whether a fresh visitor can complete the first job before you send traffic.
- Agency handing an app to a client. Give the client a replay and a repeatable acceptance check they can inspect.
- Product team changing an agent flow. Compare the same goal before and after a model, prompt, interface, or tool change.
3Method
From one job to evidence you can inspect.
3.1 Set the job
Enter a URL and one plain task. The current public service shows recorded work. New paid runs stay local and require an explicit model key and spending stop.
3.2 Send the swarm
Up to five NVIDIA Nemotron Nano visitors open separate Chromium sessions. One uses a phone viewport. They can read, click, scroll, and go back. They cannot type, sign in, pay, upload, or save.
3.3 Keep every path
The simulator saves the page text, available controls, chosen action, browser response, and screenshot at each step. Each colour on the map is one recorded visitor.
3.4 Check the claim
When a visitor says the job is complete, Nemotron 3.5 Super VL checks the final screen image and its text. Local deterministic rules also check that the required moves happened.
3.5 Return a repeatable check
A confirmed error path can become a small browser regression test. Unconfirmed claims, model failures, and unfinished visits remain visible as limits.
3.6 Run the same job after a fix
Compare the exact journey before and after the change. The longer-term goal is to test the same job with consenting people and measure where the simulation was wrong.
4Models and infrastructure
Two model roles, one inspectable handoff.
| Role | Model | Provider | Input | Job |
|---|---|---|---|---|
| The visitor | nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B | Nebius Token Factory | Page address, title, readable text, and numbered links or controls | Decide if the task is complete, then choose the next read-only browser action |
| The evidence judge | nvidia/Nemotron-3.5-Super-VL | Nebius Token Factory | The ordered path, final page text, and a compressed screenshot | Check whether copied words on the visible screen support the completion claim |
NVIDIA parts used: both Nemotron models run through Nebius Token Factory's OpenAI-compatible inference service. Chromium runs on the application host. Local task rules, evidence checks, cost reservations, and saved replays are our code. On the public Cloud Run service, the Ask Nemotron button in the studio makes one live Nemotron Nano call through Token Factory to explain a recorded run. Calls are rate-limited and capped, and each one is logged with its tokens and cost. The hosted page does not start new swarms, and no visitor text reaches a model.
5Results
The first five recorded swarms ended without a confirmed completion.
| Run | Finished (UTC) | Visitors | Stuck | Did not finish | Claimed done | Confirmed done | Steps | Model calls | Model cost (USD) |
|---|---|---|---|---|---|---|---|---|---|
| swarm-2326 | 17 Oct 21:30 | 5 | 5 | 0 | 0 | 0 | 28 | 56 | 0.0015 |
| rerun-2335 | 17 Oct 21:43 | 5 | 4 | 1 | 1 | 0 | 28 | 55 | 0.0021 |
| broken-demo-0003 | 17 Oct 22:04 | 3 | 3 | 0 | 0 | 0 | 16 | 32 | 0.0008 |
| airiq-about-404 | 22 Oct 07:24 | 3 | 2 | 0 | 3 | 0 | 16 | 35 | 0.0025 |
| airiq-about-fixed | 22 Oct 07:29 | 3 | 3 | 0 | 3 | 0 | 16 | 34 | 0.0037 |
In rerun-2335 one visitor claimed completion and the judge did not confirm it. The phone visitor in that run did not finish. The summary counts block in the two five-visitor records lists 4 visitors, one fewer than the per-visitor records; this table counts the per-visitor records. The first two runs used the working sample app; broken-demo-0003 used a deliberately broken demo app. The AirIQ runs used a real hackathon entry, cloned unedited: its About Us link answered 404; on a local fork with the page added, all three visitors opened it, and the judge quoted only the heading, so none is counted as confirmed. In airiq-about-404 the phone visitor ended as claimed, not stuck.
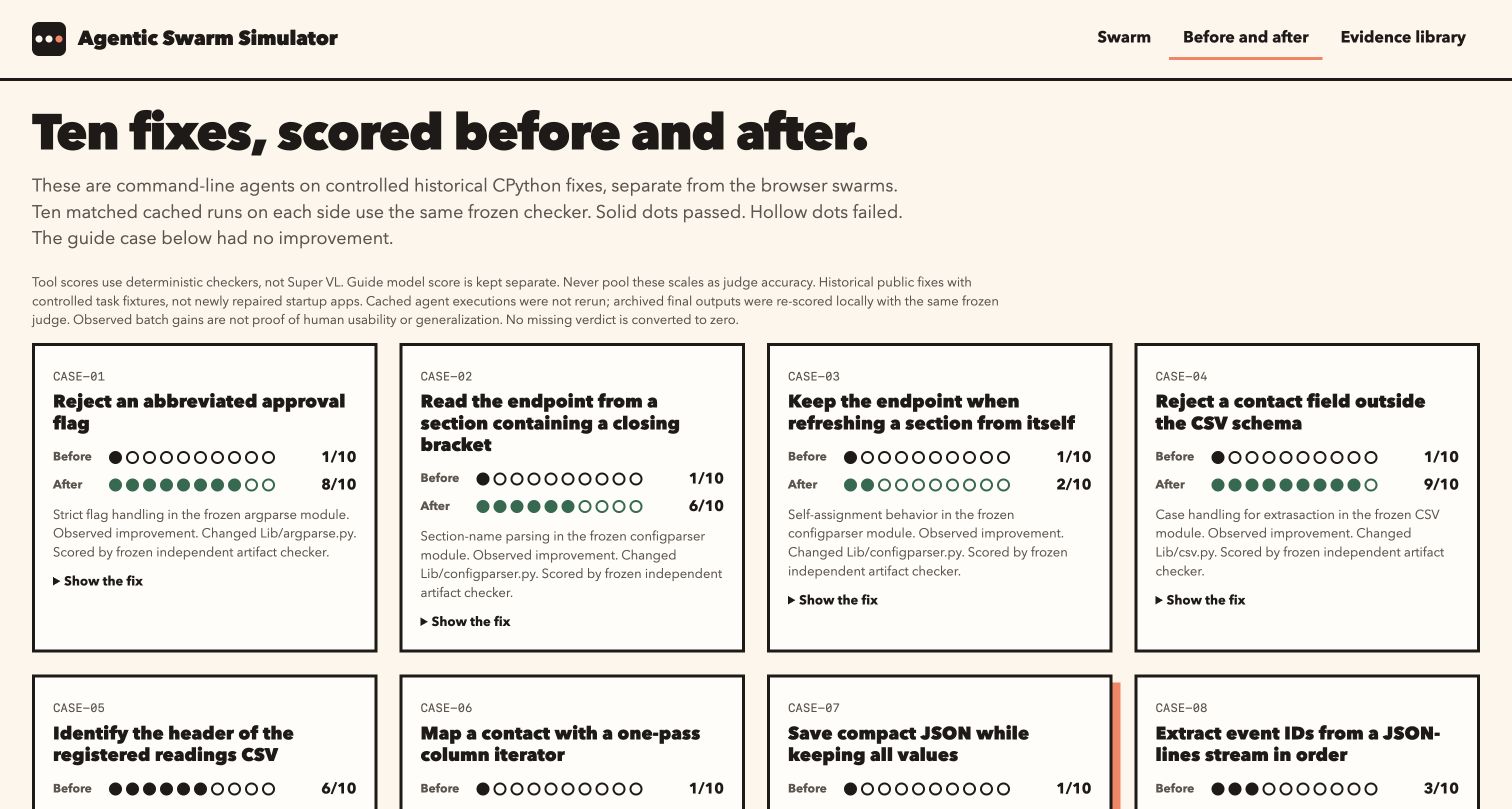
| Case | Task | Before | After |
|---|---|---|---|
| CASE-01 | Reject an abbreviated approval flag | 1 | 8 |
| CASE-02 | Read the endpoint from a section containing a closing bracket | 1 | 6 |
| CASE-03 | Keep the endpoint when refreshing a section from itself | 1 | 2 |
| CASE-04 | Reject a contact field outside the CSV schema | 1 | 9 |
| CASE-05 | Identify the header of the registered readings CSV | 6 | 8 |
| CASE-06 | Map a contact with a one-pass column iterator | 1 | 4 |
| CASE-07 | Save compact JSON while keeping all values | 1 | 10 |
| CASE-08 | Extract event IDs from a JSON-lines stream in order | 3 | 4 |
| CASE-09 | Keep visible Unicode in a release handoff | 4 | 10 |
| CASE-10 | Wrap a message without losing its hyphenated text | 0 | 9 |
| Total | 100 runs per side | 19 | 70 |
Scope, quoted from the case file: "cached real Nano command-line agents on controlled historical CPython tool fixes; not browser or human users". Tool scores use deterministic checkers, not Super VL, and are not pooled with the guide task. A judge-prompt repair on the guide task itself (CASE-11) showed no improvement.
6Live versus simulated
What this public build does today.
6.1 Live now
- This landing page and the complete recorded studio
- 15 saved browser swarms with real screenshots and model-call records [1]
- Ten cached before and after code cases with fixed checkers [2]
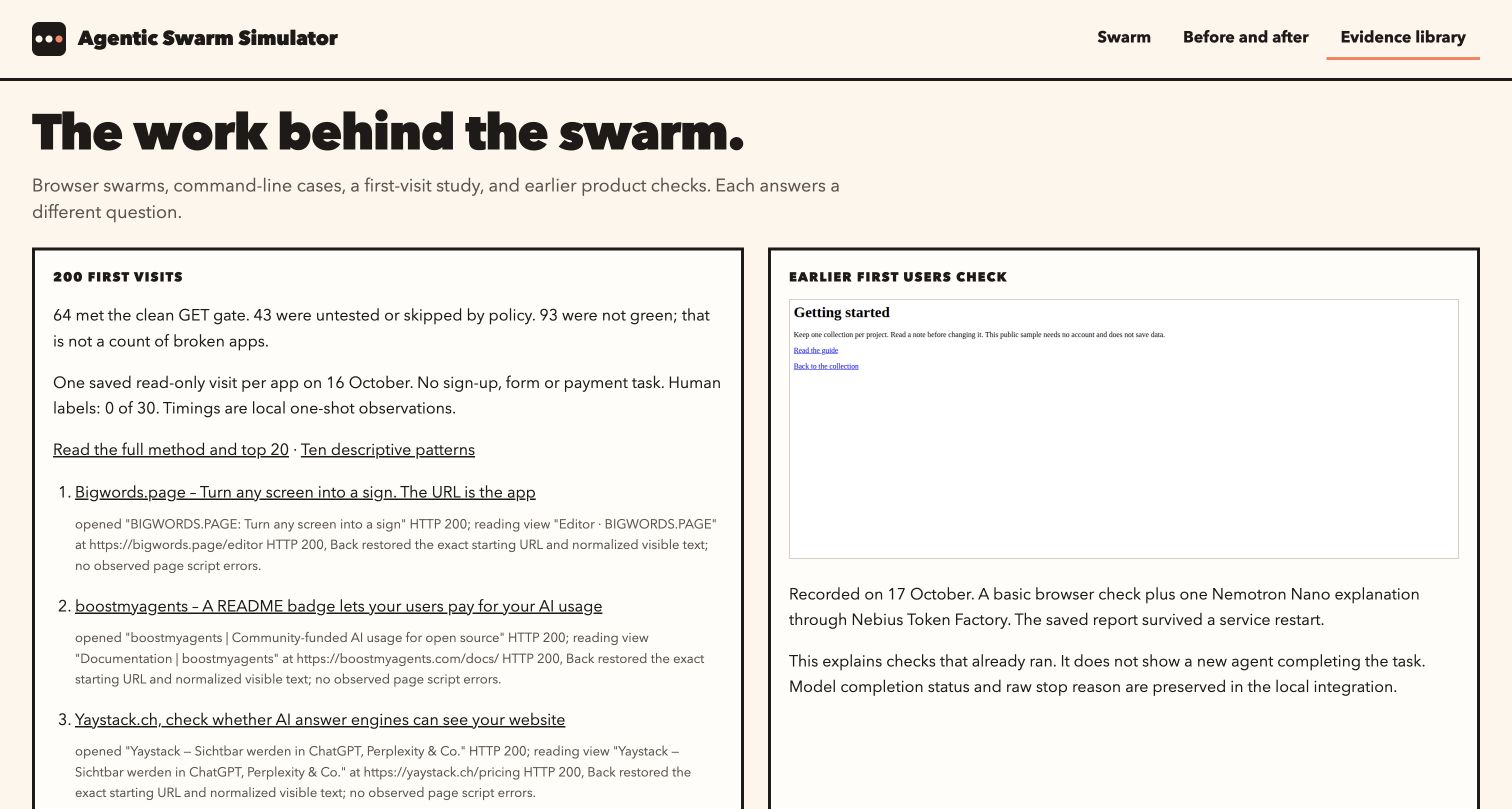
- A 200-site, read-only first-visit evidence library [3]
- Replay, path inspection, and test download with no new model call
6.2 Simulated or not yet live
7Limits
What the recorded results can and cannot show.
- Test visitors are an NVIDIA model reading and clicking your pages. They are not people, and nothing here is a quote from a real user. [1]
- They only read. Nothing was typed, no account was used, and anything behind sign-in was left untested. [1]
- Three states are kept apart. Claimed: the visitor said the job was done. Screen confirmed: a second call, given the steps and the text of that screen, agreed and pointed at words on it. Job completed: the steps also show every part the task names. The model calls can be wrong. [1]
- The ten code cases are command-line tool fixes on historical CPython code, not browser app fixes. Their gains say nothing yet about browser visitors or people. [2]
- A confirmed completion has been recorded on a real app: in the PuppyTime replay, 2 of 3 visitors opened the Donate page and the judge confirmed both. It is one app, so it shows the path works, not how often. [1]
- The first-visit study is one saved visit per app, timed once on one network. It is not a speed ranking. [3]
8Product replay
Watch the recorded studio in 75 seconds.
This replay shows the assembled interface, the latest unfinished swarm, the controlled before and after cases, and the evidence library. Playback makes no model call.
swarm-replay.mp4). No new model call is made during playback.9What comes next
Three open research steps, in order.
- Prove one complete URL to swarm to confirmed fix to rerun journey.
- Label a frozen case set and compare it with a basic browser or script baseline.
- Run the same job with a consenting outside builder.
10References
- Run records for every replay in the studio,
web/studio/fixtures/replays/<run>/result.json, each with the sha256 of its source inweb/studio/fixtures/SOURCES.json. Served at /api/studio/replays/swarm-2326, rerun-2335, broken-demo-0003, airiq-about-404, airiq-about-fixed. - Before and after case file,
web/studio/fixtures/cases.json, copied from the 17 October case run. Served at /api/studio/cases. - Show HN first-visit study, 16 October 2026: 200 apps attempted, 22 skipped before the visit by policy, 64 passed the read-only gate, 20 shown. Served at /studio/evidence/hn-first-visits.txt.
- Blind human label sheet for the same study, 0 of 30 rows filled. Local file, not in the public package.
- Nebius and NVIDIA hackathon rules on Devpost, nebiusglobalaihackathon.devpost.com, read 18 October 2026: deadline 30 October 2026, 17:00 UTC.
- The 122-app run, 22 October 2026: one record per app with each visitor's cause (
classified.jsonl), the readable check of each cause (CLUSTERS.md), and the re-judge of the 52 apps that were reached but not confirmed (rejudge.jsonl). Local lane files, not in the public package.